Data-intensive Text Processing With Mapreduce
Douban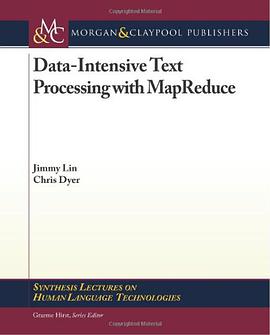
Synthesis Lectures on Human Language Technologies
Jimmy Lin / Chris Dyer
visão geral
Our world is being revolutionized by data-driven methods: access to large amounts of data has generated new insights and opened exciting new opportunities in commerce, science, and computing applications. Processing the enormous quantities of data necessary for these advances requires large clusters, making distributed computing paradigms more crucial than ever. MapReduce is a programming model for expressing distributed computations on massive datasets and an execution framework for large-scale data processing on clusters of commodity servers. The programming model provides an easy-to-understand abstraction for designing scalable algorithms, while the execution framework transparently handles many system-level details, ranging from scheduling to synchronization to fault tolerance. This book focuses on MapReduce algorithm design, with an emphasis on text processing algorithms common in natural language processing, information retrieval, and machine learning. We introduce the notion of MapReduce design patterns, which represent general reusable solutions to commonly occurring problems across a variety of problem domains. This book not only intends to help the reader "think in MapReduce", but also discusses limitations of the programming model as well.
conteúdos
1.Introduction
2.MapReduce Basics
3.MapReduce Algorithm Design
4. Inverted Indexing for Text Retrieval
5.Graph Algorithms
6.EM Algorithms for Text Processing
7.Closing Remarks